Mahalagang impormasyon
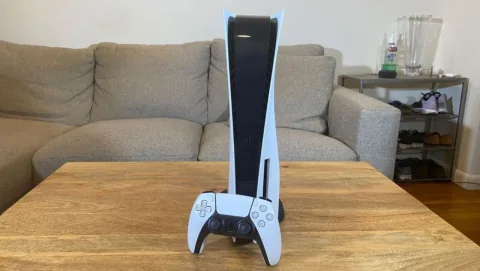
A Reddit user identified as u/AdIllustrious7246 has released a fork of PS5LM, a port of llama.cpp designed to run large language models locally on jailbroken PlayStation 5 consoles. This development enables native execution by leveraging the console's GPU, a significant advancement over previous methods that relied on CPU-based payloads.
The project utilizes PS5_Vulkan, a port of the RADV graphics driver, to bypass standard restrictions on the console's AMD-based GPU. By shifting processing from the CPU to the GPU, the system can now handle larger models like Qwen3.8-27B at 20 tokens per second, while smaller models such as Llama 3.2 3B achieve speeds of 124 tokens per second.
Native execution provides access to 11.4 GiB of RAM, a notable increase over the 6.25 GiB limit imposed by earlier CPU-only payloads that risked system instability. The updated software includes a dashboard for monitoring metrics like power draw, temperatures, and memory allocation, alongside support for a web UI that allows interaction via external browsers.
Despite the technical achievement, observers note that the PS5 hardware limitations, specifically regarding total RAM and GPU speed, make it unlikely to impact the broader AI industry. While some commenters expressed concerns regarding potential hardware demand, the console lacks the performance profile of specialized data center equipment.