मुख्य जानकारी
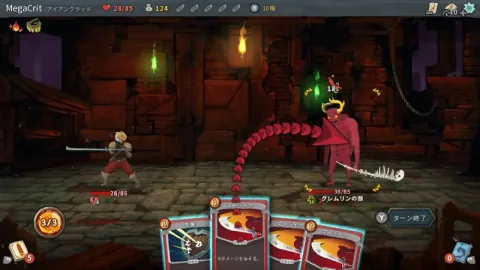
A recent preprint study by Sander W. Keemink and Scott C. Lowe evaluated 20 large language models (LLMs) playing Slay the Spire at Ascension 20. While some models successfully cleared Act 1, performance dropped significantly in later stages, with only one model achieving a final boss victory across all trials.
The researchers utilized a custom environment called SpireBench to allow LLMs to interact with the game directly. To mitigate prior knowledge, the study replaced in-game terminology. Performance was compared against Mega Crit’s historical data and four veteran streamers, revealing that while top LLMs can outperform average players in short-term combat, they fall short of expert human proficiency.
The study attributes the LLMs' failure to their overly cautious playstyle. Models prioritized immediate HP preservation, frequently choosing rest over card upgrades and avoiding elite encounters. Furthermore, LLMs tended to acquire too many cards, bloating their decks. These behaviors contrast with expert strategies that balance risk and long-term growth.
The authors acknowledge limitations, including small sample sizes and the inability to fully exclude general deck-building knowledge. Despite these constraints, the findings highlight that even advanced AI models struggle with the complex, high-stakes decision-making required to master the game's highest difficulty.